The Mo Blog

Benchmarks, architecture, governance, and field notes for teams putting coding agents and AI models into production.

Latest

Featured article
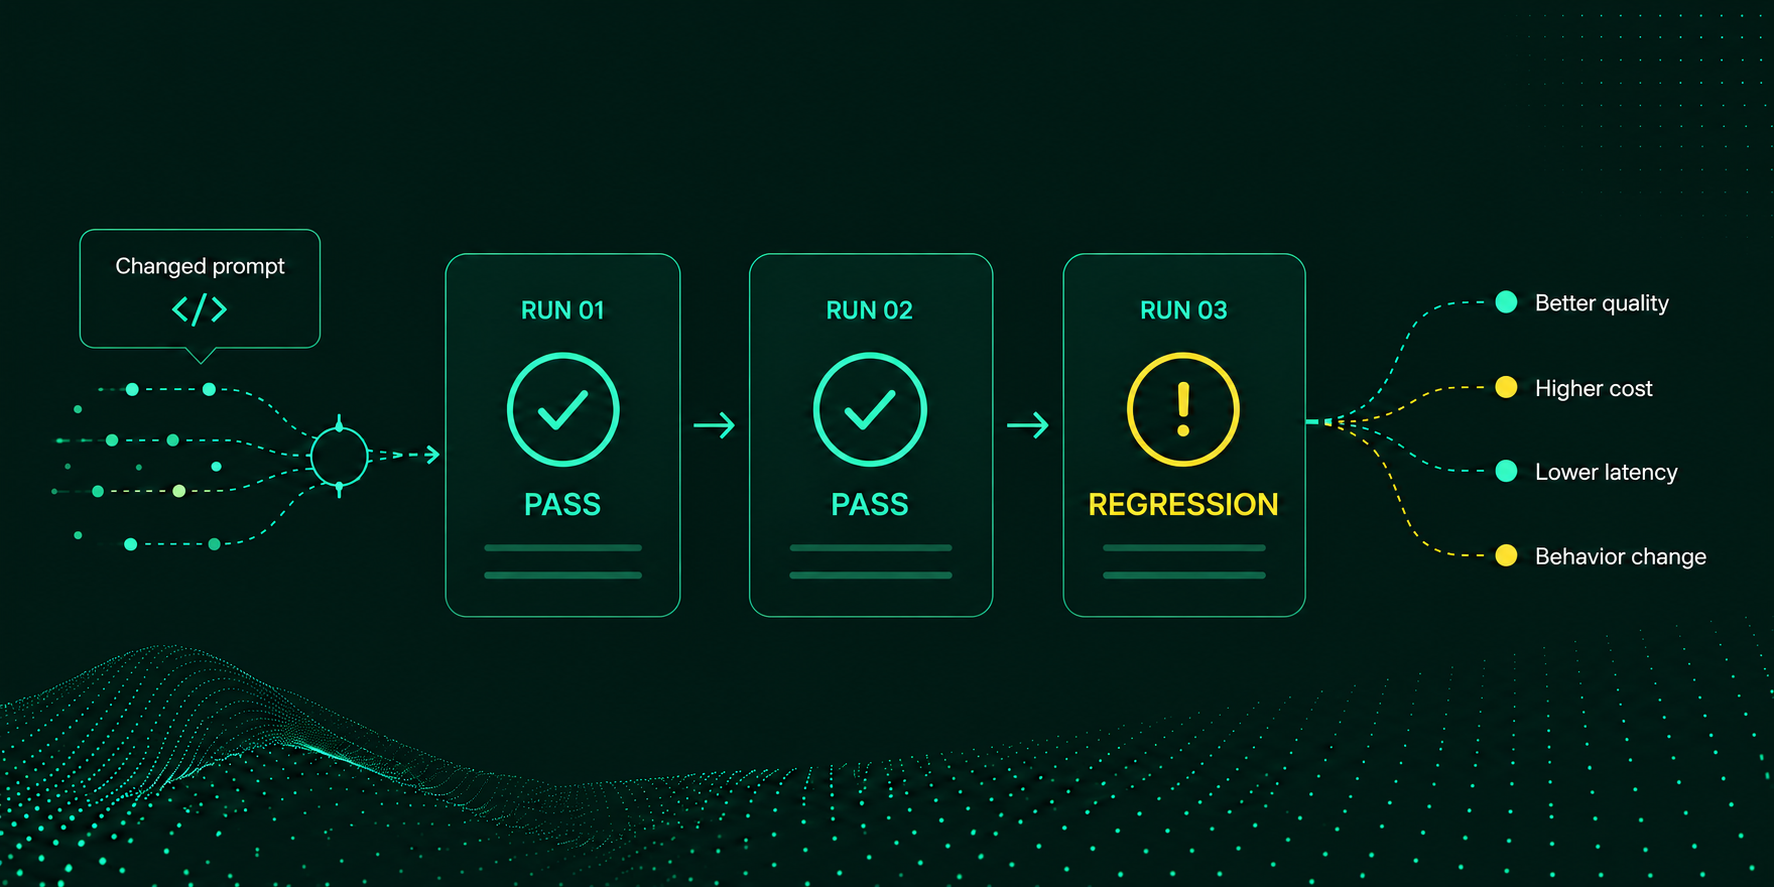
Changed prompt evaluated across three runs, revealing changes in quality, cost, latency, and behavior

AI · mo eval · inference · August 27, 2026

Verifying AI toolchain updates is hard

Every change to a harness, a coding agent, a model, a prompt, a tool policy, is a bet that it made things better. Here's what it actually takes to know there was an improvement, and why most teams can't answer that today.

Read article →

All articles

Verifying AI toolchain updates is hardMike Callahan Comparing AI toolchains is easy, but can you trust the results?Mike Callahan and Mike Landis Eval scripts are not production-ready infrastructureMike Callahan and Mike Landis mo's gateway isn't new. The traffic is.Mike Callahan Introducing mo: the enterprise control plane for AI modelsDaniela Miao and Khawaja Shams